

Intelligence at every power level
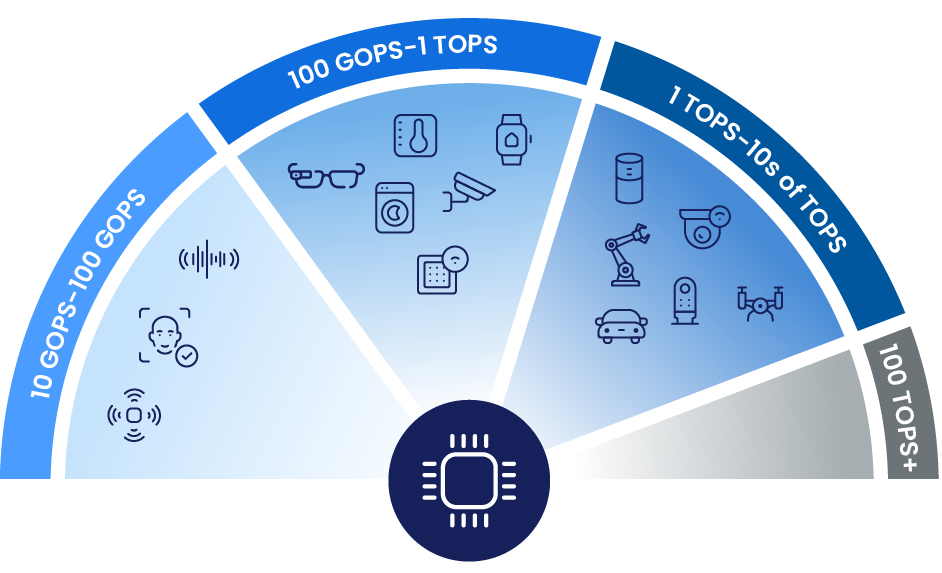
Astra pairs NPUs and GPUs with scalable MPU and MCU compute, so you can fit on-device AI to the power and performance budget of your product.
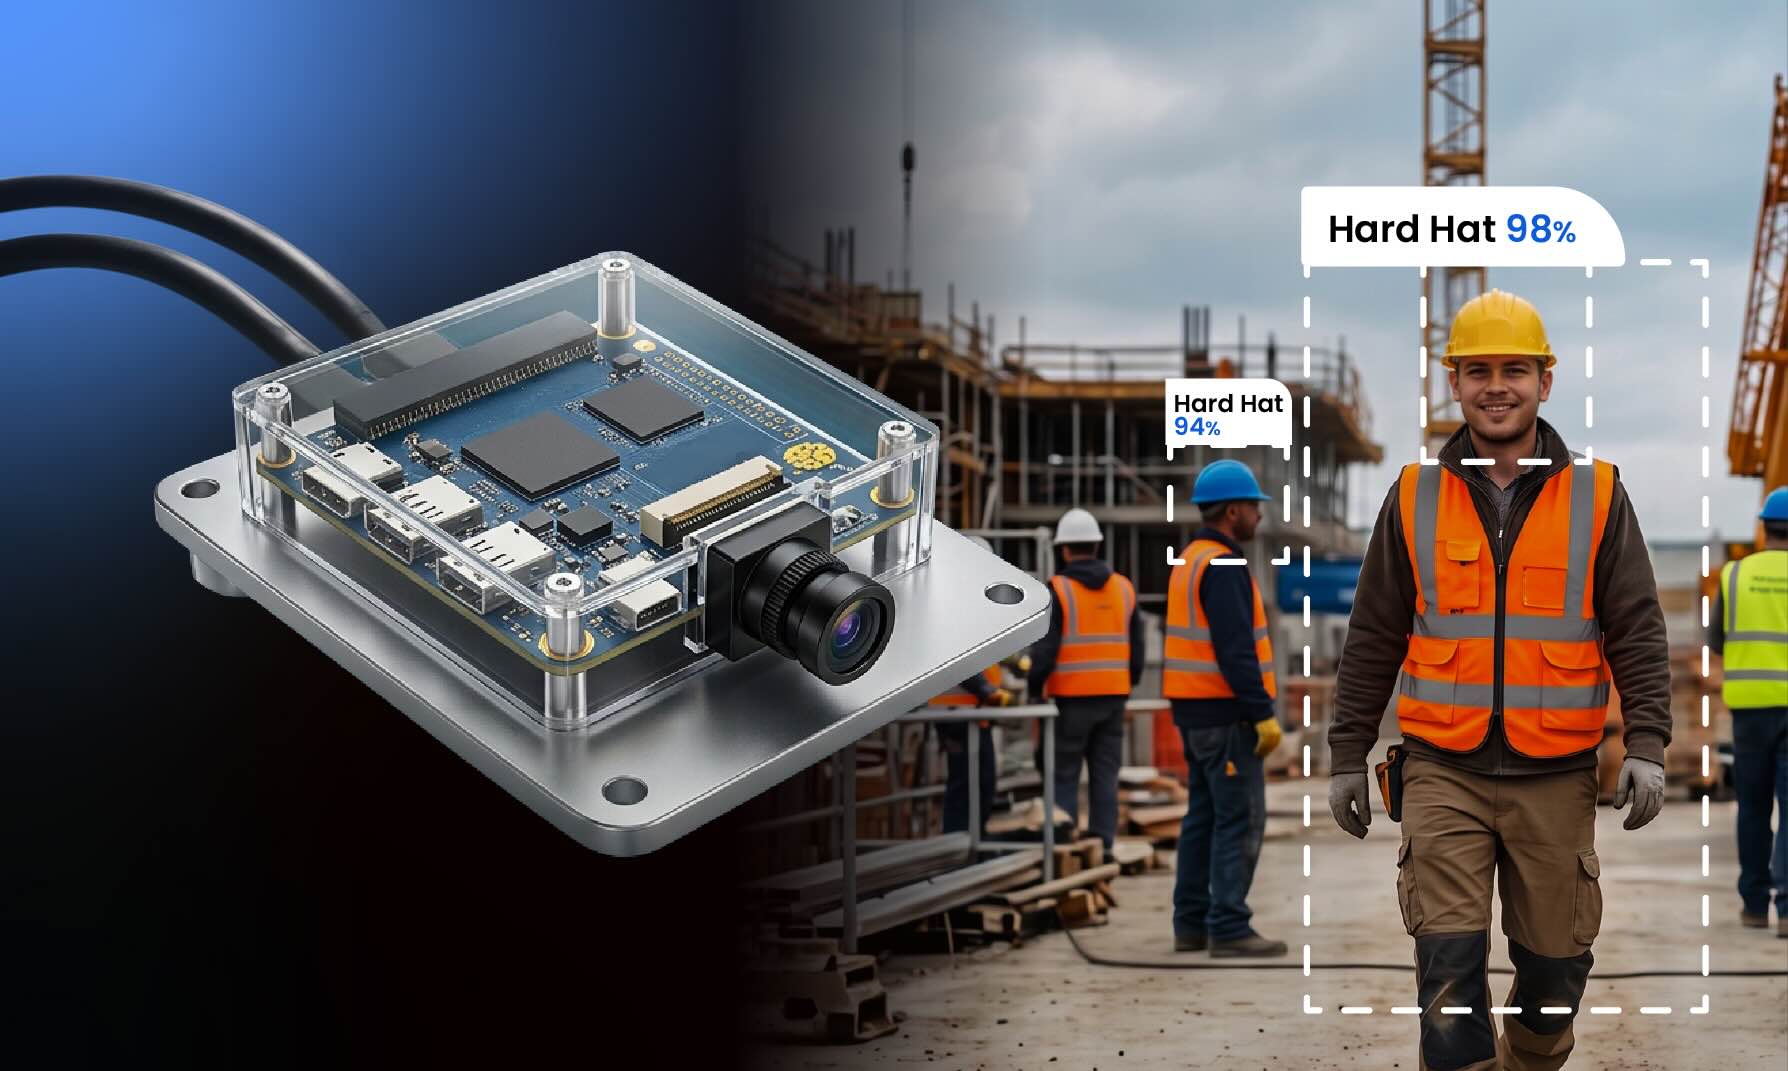
Prototype with deployment in mind, with Synaptics Coralboard™, powered by the open-source Torq™ Edge AI Compiler with Coral NPU from Google Research.
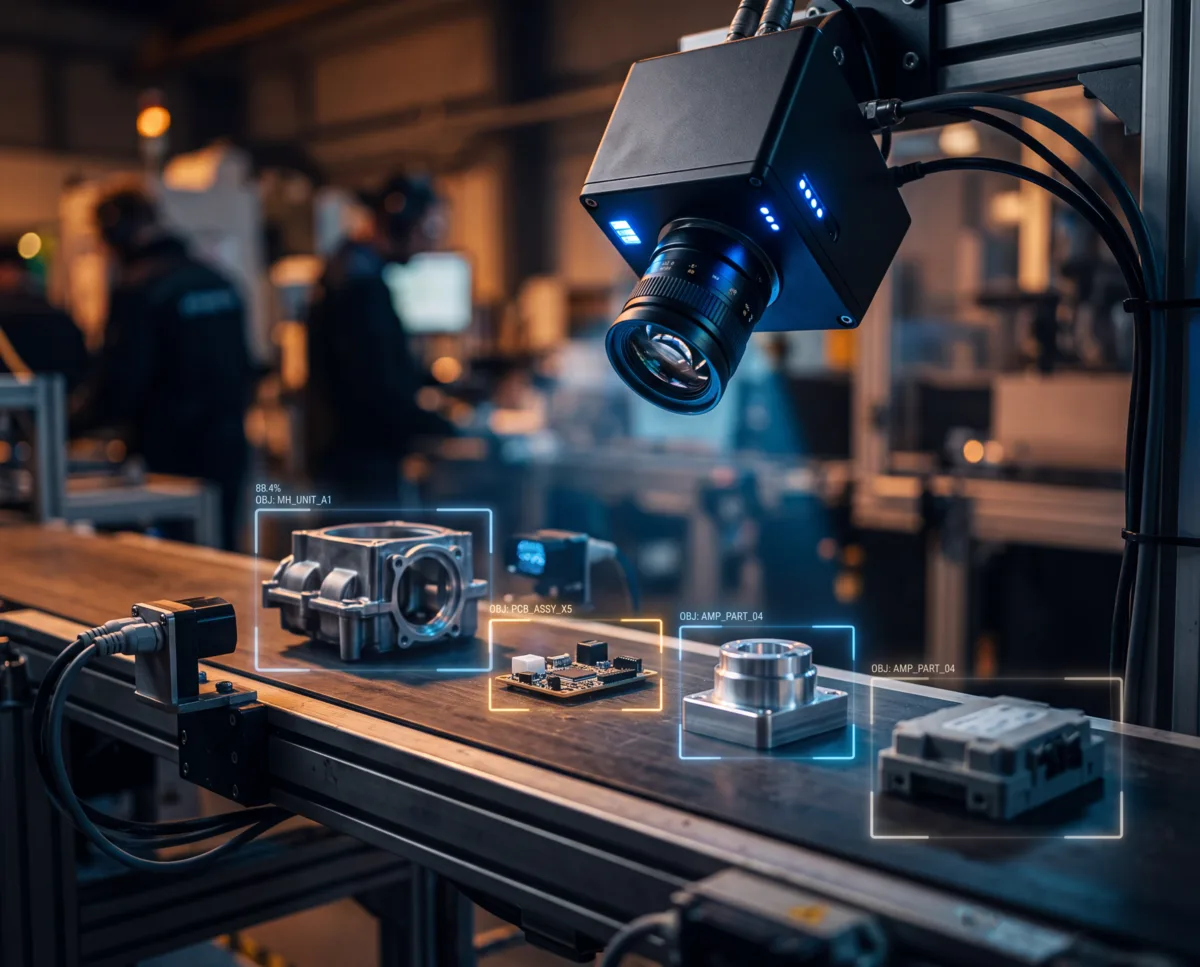
Access optimized AI models for vision, audio, language, and multimodal workloads running on Astra. Explore models, reference implementations, and development resources to accelerate application development and bring intelligent experiences to market faster.
View development guides, application examples, and best practices from the Astra ecosystem. Discover how developers are optimizing AI models, deploying applications, and bringing innovative edge AI solutions to life.
Accelerate development with practical tutorials covering platform bring-up, AI workloads, application development, and deployment on Astra.
Astra pairs NPUs and GPUs with scalable MPU and MCU compute, so you can fit on-device AI to the power and performance budget of your product.
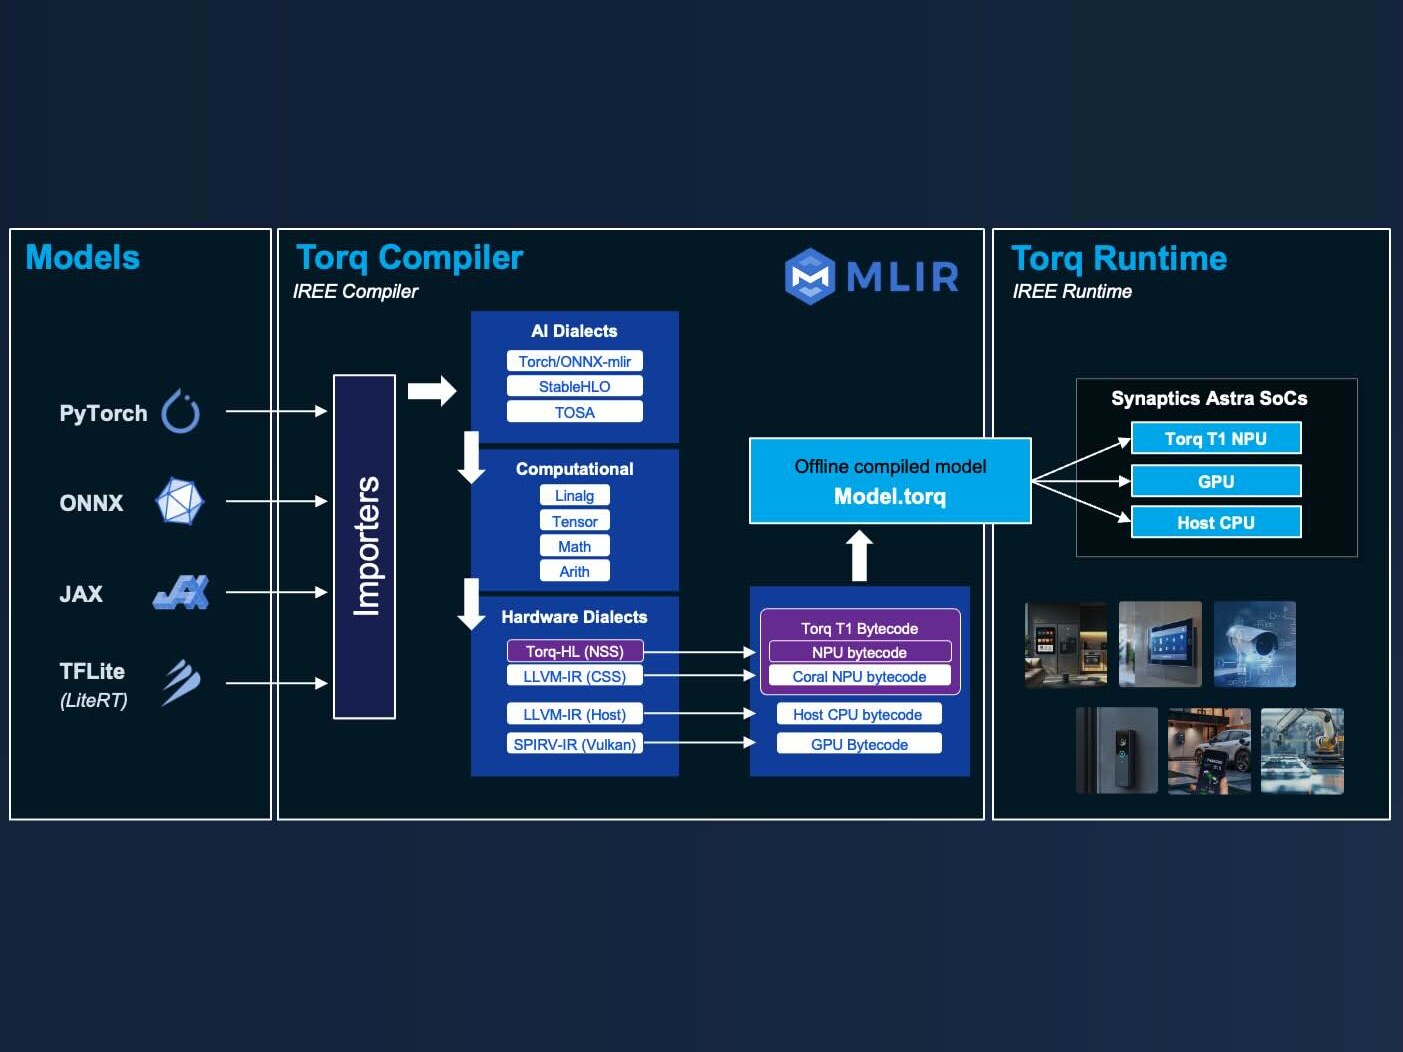
Synaptics Torq with Coral NPU adds flexibility through software updates, so devices keep up with new models without new hardware.
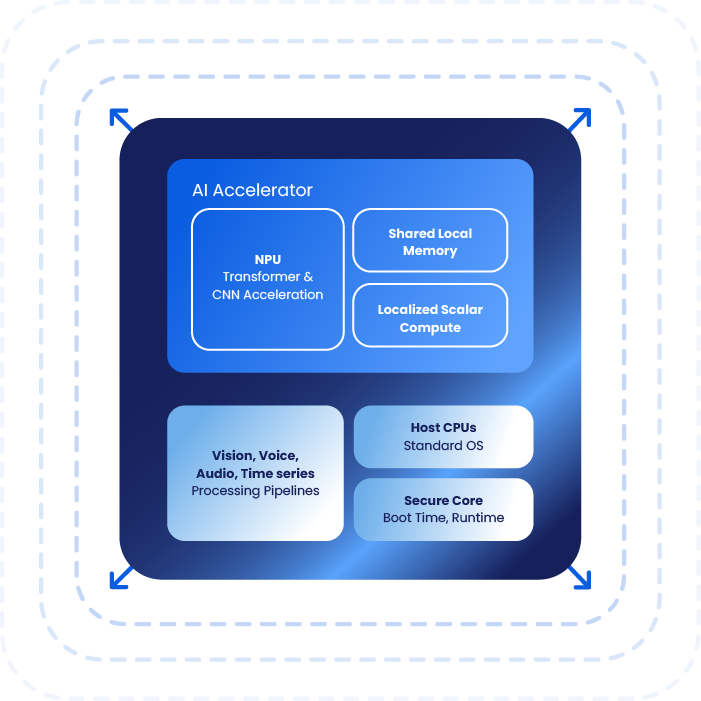
INT8, INT4, mixed precision and ultra-low 1.58-bit quantization, plus hardware-aware tools that map models onto the NPU and GPU, help you balance speed, accuracy and memory.
Pick from models already optimized for Astra, or compile your own PyTorch, ONNX, JAX or TFLite model with the Torq or SyNAP compiler.